Deep Learning–Based Video Stabilization

Tarun Gangadhar Vadaparthi

Demo

Side-by-side comparison: raw vs smoothed camera motion using learned sequences.

Abstract

We estimate dense optical flow with RAFT and collapse it to mean (dx, dy) per frame pair. A BiLSTM (with Transformer/GRU baselines) is trained to predict smoothed motion sequences supervised by a local moving-average target, reducing jitter and improving visual stability.


Method Overview

Pipeline: RAFT → mean flow → sequence model → smoothed motion
Pipeline: RAFT flow → mean (dx, dy) → masked MSE training on moving-average targets.

Results

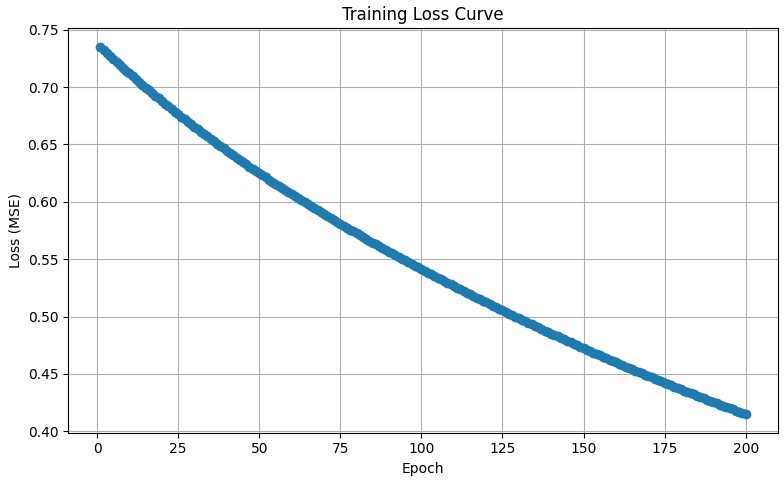
Training loss curve
Training loss (example).
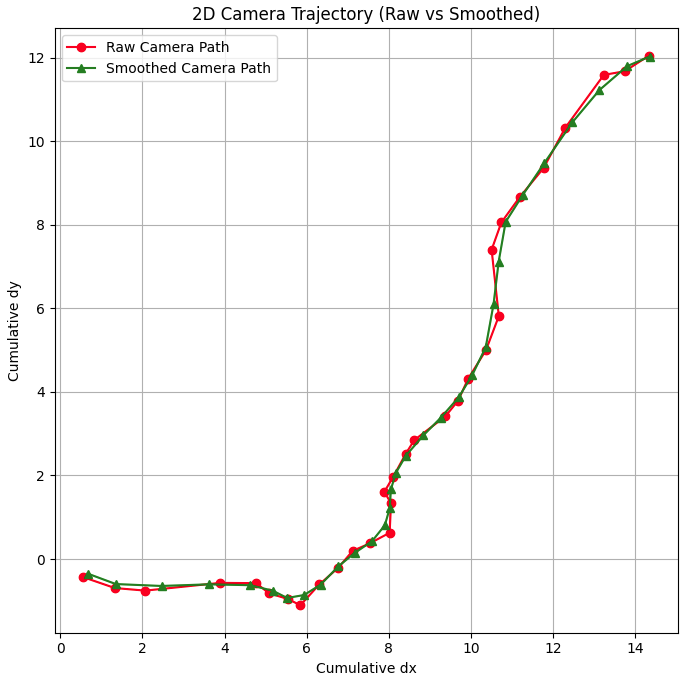
2D camera trajectory (raw vs smoothed)
2D camera trajectory: raw vs smoothed.
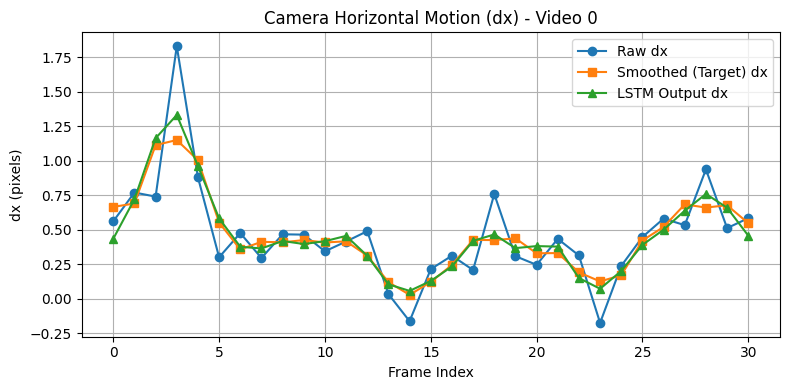
dx/dy time series (BiLSTM)
Per-axis motion (dx/dy): raw vs target vs BiLSTM.
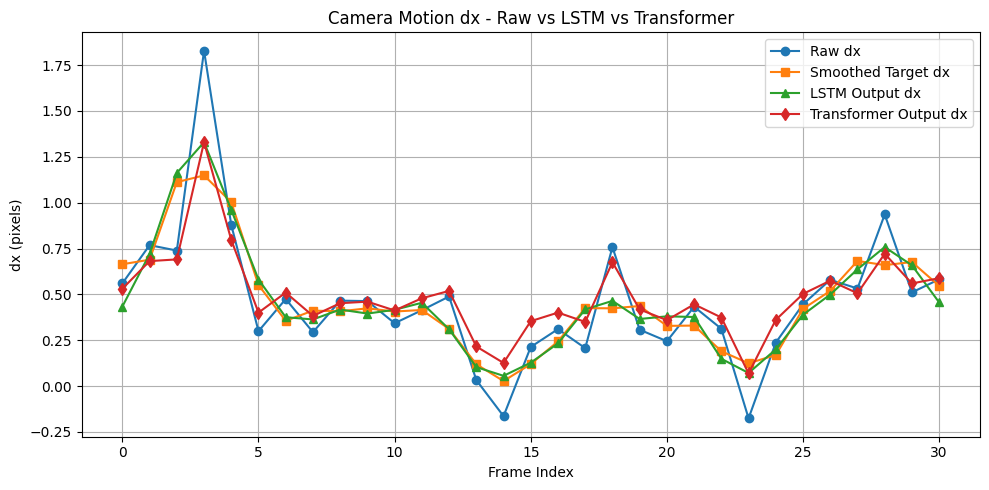
Model comparison
Model comparison: BiLSTM vs Transformer vs GRU.